
How AI Anomaly Detection Catches the Problems Your Tests Miss
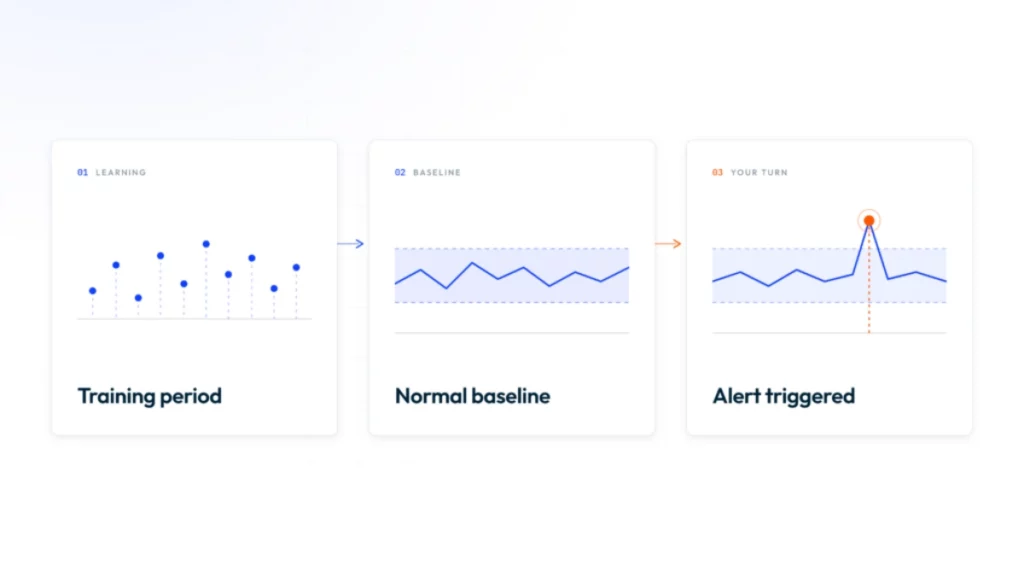
Your test suite is a record of every failure you’ve faced. You wrote a test because something broke once, and you never wanted it to happen again. Which is great, except it means your tests are always backward-looking. The failures that actually keep you up at night are the ones that no one on your team thought to check for, because it’s impossible to anticipate them until they happen.
This is the gap AI anomaly detection is built to fill. AI anomaly detection is the use of machine learning to automatically learn what “normal” looks like in your data, so it can flag anything that deviates from that pattern without a human having to write the rule first. No more hand-written thresholds and no more waiting for outages to know what to watch for.
To understand how it all works (and to figure out whether you should build it yourself or buy it) you need to know three things: how models define “normal,” what counts as an anomaly, and why context changes everything.
What Is AI Anomaly Detection?
At its core, AI anomaly detection is just pattern recognition. A model watches your data long enough to build a picture of typical behavior, then signals whenever something doesn’t fit. Most of this work happens on time series data like error rates collected over time where the model picks up on trends, cycles, and seasonality so it can spot what doesn’t belong.
Here’s a quick AI anomaly detection example to make this concrete. Say your orders table usually adds about 50,000 rows a day. One Tuesday, only 8,000 are added. A static threshold set at “alert below 10,000” would catch it, but it would also fire every Sunday when volume naturally dips. An AI anomaly detection model that has learned the weekly rhythm of your traffic knows Sunday dips are normal. A Tuesday dip? That’s a different story. It only alerts when the drop actually matters.
That’s the real difference between this approach and traditional testing. Tests catch the “known unknowns,” the problems you already anticipated. The really costly failures are the “unknown unknowns” that don’t even have a test yet.
Three types of anomalies
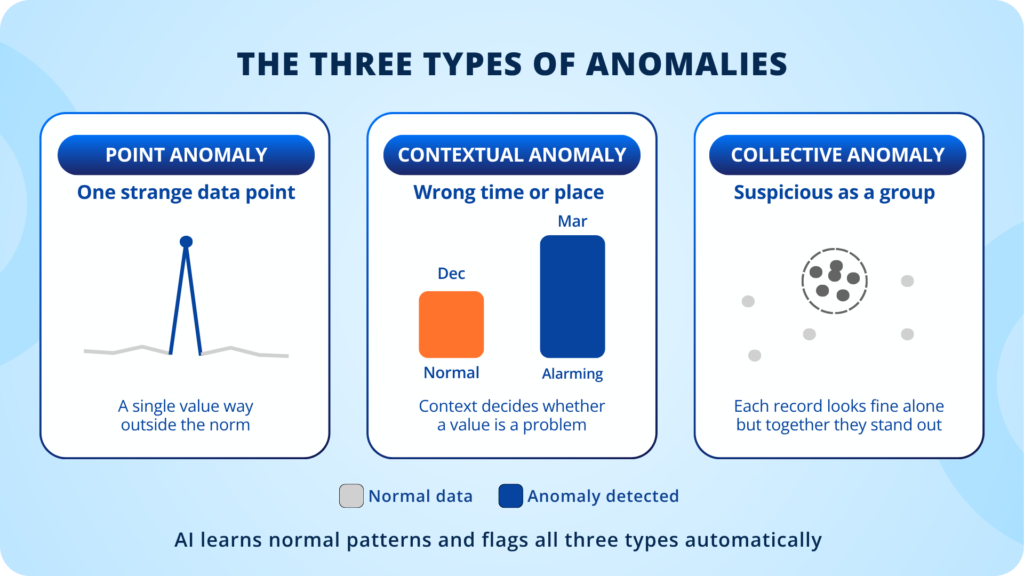
Anomalies aren’t all the same. There are three main types to know:
- Point anomaly — a single weird data point that sticks out on its own.
- Contextual anomaly — a value that would look fine in one setting but is alarming in another, like a traffic spike that’s expected in December but suspicious in March.
- Collective anomaly — a group of records that each look fine individually but form a strange pattern together.
This sort of context is the real upgrade over static thresholds. Instead of treating every number in isolation, the model understands your seasonal patterns and adjusts accordingly.
Best of all this detection layer runs on machine learning and statistics, not large language models. That means each flag is a focused, statistical judgment rather than a generative guess. LLMs do play a role in modern platforms, but they are more complementary in the stack, powering agents that recommend what to monitor or help you resolve issues after they’ve been flagged.
Building Your First Detector
Start with one painful problem
The temptation is to monitor everything from day one. Resist it. Pick one painful, specific problem you’re already dealing with such as a table that you find occasionally goes stale, or a pipeline that happens to drop some rows overnight. Starting narrow lets you prove value fast and learn the ropes before you scale up.
Get your training data in order
You’ll need a decent chunk of clean historical data for the model to train on. Time series data spanning at least a couple of months is ideal, so the model can learn weekly cycles and end-of-month spikes that would throw off a shorter training window.
Pick your approach: supervised vs. unsupervised

Your approach mostly comes down to what labels you have. If you already know what “bad” looks like with past incidents tagged as anomalies, a supervised model can learn from those examples. But more often you won’t have neatly labeled data, and that’s where unsupervised methods come in. They figure out the boundaries of “normal” on their own. Most tooling presents this as a choice between automated thresholds the platform learns for you and manual ones you set yourself.
AI anomaly detection tools to get started
If you’re going the DIY route, Python has some solid starting points:
- Scikit-learn offers algorithms like Isolation Forest and One-Class SVM for general anomaly detection.
- Meta’s Prophet is a go-to for time series forecasting that can surface unexpected deviations.
- AWS Lookout for Metrics and Azure Anomaly Detector are cloud-managed options that handle the infrastructure for you.
- Monte Carlo provides AI-powered anomaly detection purpose-built for data quality and pipeline reliability, without the build-it-yourself overhead.
Whatever path you choose, be realistic about tuning. Every threshold you set by hand is one you’ll be re-setting by hand as your data changes. Near-zero threshold configuration should be a baseline requirement for anything that needs to scale.
Wire alerts to where your team actually works
Don’t forget the last mile: send notifications to wherever your team actually works, be it Slack, PagerDuty, or an on-call rotation. A warning that no one sees is the same as no warning at all, and make sure to attach enough context that whoever gets pinged knows what happened and what to do next quickly without having to start an investigation from scratch.
Getting the detector built is one thing, though. Keeping it useful three months later is where most teams hit a wall.
Where AI Anomaly Detection Systems Break Down
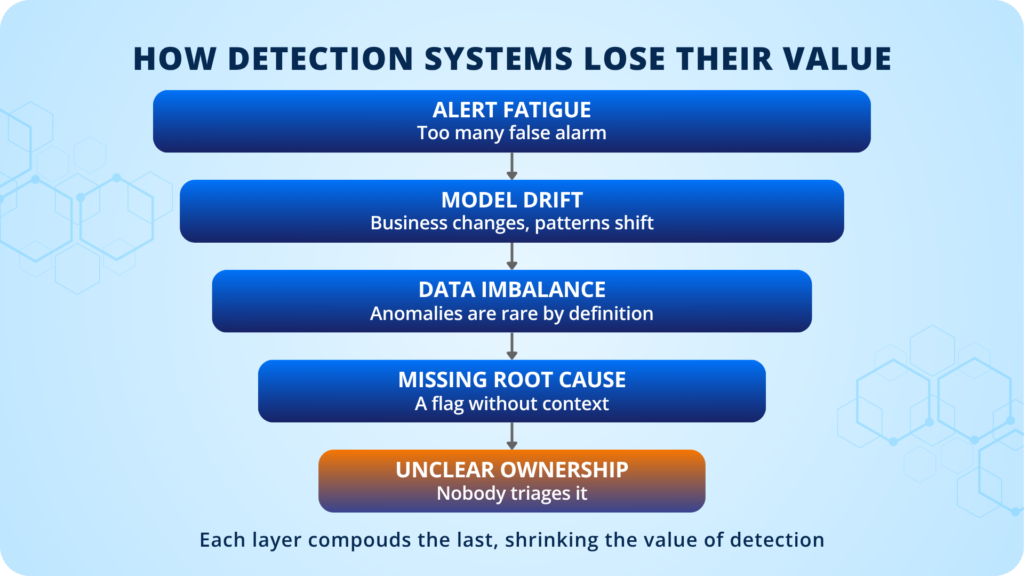
Alert fatigue
Alert fatigue is the number one killer. It doesn’t matter how smart your model is if nobody reads the alerts anymore, which is exactly what happens after too many false alarms. Once people start ignoring notifications, you’ve effectively turned off your monitoring.
Model drift
A detector trained on last year’s traffic patterns might cry wolf about this year’s perfectly healthy growth. What looked abnormal six months ago could just be your new baseline, and if the model hasn’t been retrained to reflect that, you’ll drown in false flags about completely expected behavior. This is the same challenge that plagues ML models across the board—what some call data drift.
The rarity problem
Anomalies are rare by definition, and that also means there aren’t many examples for a model to learn from. Measuring accuracy gets tricky when the thing you’re looking for almost never happens.
Flags without root cause
Even when your detector catches something real, a flag without a root cause is only half an answer. You want to know why a number looks weird and what it touched downstream. Did a source system go down? Did someone push a bad schema change? Without that context, your team is still spending a lot of time playing detective.
Ownership gaps
Someone needs to be clearly on the hook for triaging issues that get flagged. If ownership is fuzzy, no one will take the responsibility to actually get a fix built and the problem will linger.
All of which points to a bigger idea: anomaly detection on its own is just one piece. To really keep your data reliable, it needs to sit inside a much broader strategy.
Why AI Anomaly Detection Needs Observability
Catching a weird number is useful. Understanding why it’s weird and what else it broke takes end-to-end visibility across freshness, distribution, volume, schema, and lineage. That’s exactly what data observability provides, and it’s the layer that turns anomaly detection from isolated alerts into real answers.
Monte Carlo applies machine learning across all five pillars automatically, so you get AI-powered anomaly detection from day one. On top of that sit platform agents like a Monitoring Agent that recommends rules you can deploy with one click, a Troubleshooting Agent that investigates root causes and recommends next steps, and an Operations Agent that ties it all together through natural language. When an alert fires, end-to-end lineage maps the blast radius instantly, showing you the upstream source that broke and the downstream tables, dashboards, and stakeholders it hit.
And as your stack expands into LLMs and AI agents, data and AI observability extends that same coverage across data, system, code, and model response, while agent observability monitors the four pillars of agent trust: context, performance, behavior, and outputs.
If you want to see how all of this works together, grab a demo by entering your email below.


