
Inside Monte Carlo’s GTM Hub: How We Run our Revenue Team on AI Agents
With the proliferation of AI across businesses for internal use cases, teams are quickly spinning up agents to take on many of the tasks that humans used to do. With that inevitably comes some operational chaos.
Walk into almost any go-to-market org today, for example, and you will find the same thing we found when agentifying our GTM workflows at Monte Carlo: dozens of reps running hundreds of private AI sessions. An account executive drafting outreach in one tab, while a CSM summarizes a renewal in another, and in yet another an SDR researches an account before a call. Every one of those sessions is useful, but none of them actually compound to make the team as a whole better.
The work lives and dies in a private window, and so the good prompt one rep perfected never reaches the rep next to them. Not only can GTM team members not see what the others are doing for learning purposes, but none of them can see the risk, either: customer data is pasted into a dozen tools with no audit trail and no owner.
At Monte Carlo, our entire existence is dedicated to building software that tells enterprises whether they can trust their data and their AI. We were not going to run our own go-to-market on untrustworthy AI. That is why we built the GTM Hub.
Individual AI saves time, institutional AI scales revenue
The conviction that drove this project forward is simple: individual AI saves a person time, but it’s institutional AI that scales a company’s revenue. The difference is having a coordination layer, the thing that turns one rep’s clever workflow into something the whole org runs, the same way, with the results visible to everyone and the cost on a dashboard.
Without that layer, you are buying a thousand individual productivity boosts and no institutional advantage. You are also buying a thousand ungoverned risks. We built the GTM Hub as our coordination layer.
What the GTM Hub is
The GTM Hub is a single, governed front door for AI across our entire go-to-market motion. Account executives, CSMs, field engineers, SDRs, and their managers all enter through the same surface, and each lands on a home built for their role. A growth AE and a post-sale field engineer see different cockpits without having to configure anything themselves.
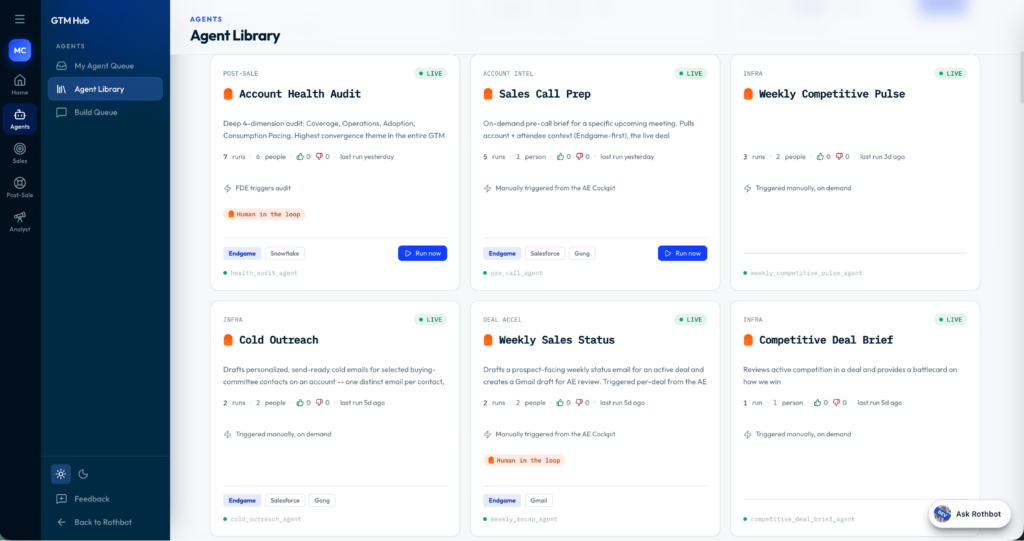
Inside, agents do the work, triggered from the account or deal in front of the rep. In this way, running a governed agent is actually easier than opening a private Claude session, not harder. And every proven workflow is presented back to the org as a catalog anyone can browse, run, and upvote. The best workflows rise to the top, and so the GTM org gets smarter as a whole system, not as a scatter of individuals.
What that looks like in practice
Here’s a typical workflow in the GTM Hub: an account executive opens the Hub and lands on her home, already scoped to her book of business, with priority accounts ranked, and anything that changed overnight getting surfaced first. Ahead of a call with a prospect she runs the Account Research agent, which returns the company’s structure, recent news, and the likely data-trust pain that maps to our product. Just before the call she runs Pre-Call Prep, which turns the last few conversations, the open opportunity, and the account’s health into a short talk track.
Later she has another prospect to reach out to cold. She runs the Cold Outreach agent from inside the account, edits the draft, and hands it to our sequencing tool to send. After lunch she flags an at-risk customer to the CSM who owns it, who runs the Account Health Audit, our most thorough workflow, and gets back a full written assessment of the account’s usage, adoption, and consumption. That audit used to require hours of manual analysis when it was human-driven. Now, it’s completed in a single run.
Every one of those agents ran under a real person’s identity, read from the same source of truth as the rest of the org, and logged what it did. Nothing operates in a private window anymore.
Why we built it instead of buying it
The obvious question: why not just hand everyone a great desktop AI tool and move on?
The answer here is that ungoverned AI fails in predictable ways, and we understood this from the get-go.
Where proven workflows get forwarded around in a dozen versions with no single source of truth, our Hub prevents this. We keep one curated library with a canonical version of each agent, ranked by what the field finds useful.
We built shared cockpits reading one governed data replica, where everyone sees the same numbers scoped to their own book.
Every agent in the Hub also triggers from inside a named workflow under the caller’s own identity, carries an upvote and feedback loop, and reports its cost per run to the people accountable for it.
Off-the-shelf governance platforms exist, and some are good. But governing our go-to-market meant governing our data, our roles, and our workflows, so we built the front door natively and put it where the work already happens.
How we built it: an engine and a surface
We followed a multi-layered architecture.
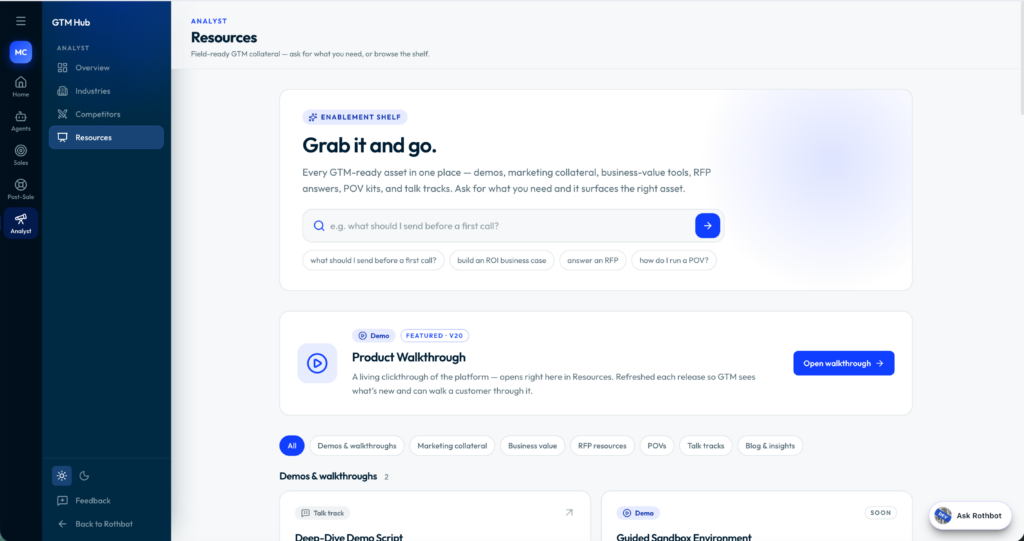
The surface is the GTM Hub itself: the cockpits, the library, the persona-routed home, and the chat. The engine underneath is a platform we call Armada, and Armada is deliberately not an agent runtime. It is a governance and workflow layer built on top of Anthropic’s Claude Managed Agents, the hosted runtime that actually runs each agent. Everything in Armada runs on that runtime underneath. There is no second, home-grown engine to maintain.
That choice was intentional. We did not rebuild the parts Anthropic already does well: the model, the tool use, the sandbox, and the session loop. We spent our effort only on the parts that make an agent institutional instead of individual: a shared catalog of admin-curated canonical agents, multi-step workflows with human checkpoints, single-sign-on identity on every run, shared connections to Salesforce, Gong, Slack, and our warehouse instead of every rep wiring their own, and a full logged history for audit and cost.
Put plainly: the base runtime gives you a smart agent. Armada turns a smart agent into a governed, shared, accountable one. The Hub is where the field meets it.
Two more principles shaped the build.
- First, encode the workflow, don’t assist a human through it — use the model for reasoning and code for the rules, so an agent is a repeatable workflow, not a chatbot someone has to steer every time.
- Second, let the field promote the winners — a workflow one person proves by hand becomes a governed agent the whole org runs, chosen by upvotes, not by committee.
The brain underneath: a knowledge fabric
An agent is only as good as the context it reads, and here we hit the deepest version of the sprawl problem.
When we went looking, our go-to-market knowledge — who our ideal customer is, how we position against a competitor, what a persona cares about — lived in several tools at once, each drifting from the others. If agents read from that, they inherit the contradictions.
So underneath the Hub we are building what we call a knowledge fabric: one canonical store of Monte Carlo’s reusable go-to-market knowledge, written once, in plain text, version-controlled the way engineers version code. The fabric is the single brain; the library, the cockpits, and our research and sequencing tools read from it instead of keeping their own copy.
We are honest that the fabric is still being wired in, and thus the project in its entirety is still a work in progress. The canonical store and its content are real, but the automated pipeline that pushes every edit to every agent is still in build mode.
What a 2.6-million-token morning looks like
We are serious about the performance of our internal agentic tools at Monte Carlo, just as we are committed to helping our customers optimize their own systems. Every agent in the Hub is, therefore, instrumented to monitor cost, latency, the tools it called, the quality of what it produced, and every run is logged against the person who triggered it.
Having this level of visibility into the Hub paid off almost immediately.
Here is an example.
Our Weekly Sales Status Digest agent researches an opportunity and writes a status summary. It normally runs on roughly 200,000 tokens. One morning a run came in at 2,617,798 — twelve times its usual cost.
The trace showed the shape of the problem immediately. The agent was supposed to read account context from our context-graph provider. On that run, the graph tools came back “restricted.” So the agent improvised: it fell back to querying our BI tool instead, ten-plus times, hammering it for context it was never going to find there. Nothing errored or alerted, and it did produce an answer in the end. It just spent twelve times the cost and three extra minutes to get there, and it had picked its data source on a whim.
That last part is the actual problem, and it’s not just a cost problem, but also a trust problem. An agent silently swapping its source of truth is exactly the failure mode we built our company to catch in data pipelines, showing up one layer higher.
The fix was one line: an explicit constraint telling the agent never to call the BI tool, not even as a fallback. We had told the agent which tool to use, but not which tools were forbidden — and with agents, naming the right tool is not the same as banning the wrong ones.
We re-ran the identical opportunity to check. 205,315 tokens instead of 2,617,798. Six model calls instead of twenty-plus, which is a 92% reduction in cost on that run from a single line of instruction, found by looking at a trace.
Without that level of visibility we would never have known.


Running some numbers
In a recent 30-day window, every AI agent our go-to-market org ran cost $251 in total across 323 runs — an average of $0.78 a run. These figures are not a run-rate: we only started measuring recently, and adoption is still ramping. That number will go up.
The durable part is the relative shape, which barely moves. Our deepest workflow, the Account Health Audit, runs at roughly $3.33 because it reads a lot and writes a full assessment. Almost everything else costs cents: Cold Outreach about $0.40, Industry Research $0.36, Account Research $0.31, Pre-Call Prep $0.23. The expensive agent is the one doing hours of analyst work. The cheap ones each save a rep minutes, many times a day.
Read that against the thing everyone actually fears about AI adoption: the untracked five-figure surprise invoice. Part of why we are able to control costs is that we have governed intelligence embedded in the daily motion. When you can see every run, own every run, and price every run down to the agent, cost stops being a fear and becomes a number you manage.
In the last 30 days, nearly a third of our field sales and engineering org (29%) ran at least one agent, and more than half of everyone who tried one (56%) came back and ran another. This is still an early internal rollout, and we are wiring up deeper adoption instrumentation as we go, but the shape is the one you want: reps returning to a tool because it earns the next click, not because they were told to.
Four lessons for anyone doing this
- Institutional beats individual only if the workflow and the context are shared. The unlock for our GTM team was to create one front door where a proven workflow becomes available to everyone, reading from one brain instead of many drifting copies.
- Instrument the agents before you scale them. Every hour we have spent on observability has paid for itself in a single trace, as is evident from our example of the agent run that cost twelve times too much. Things like that kill the program.
- Publish what you can defend. We have an acceptable cost per run, a repeat-usage rate, and a trace for every decision an agent made. That is a less exciting headline and a much better foundation.
- Governance is an adoption strategy, not a tax. A governance layer nobody opens governs nothing. We won adoption by making the governed path the path of least resistance, meeting reps inside the cockpit they already live in.
Where this goes
The GTM Hub is how Monte Carlo turns AI from a personal productivity tool into an institutional revenue system: one governed front door, one shared brain, every run owned, measured, and improvable.
It is also the same conviction that drives our product. As the world moves to agents, the winners will be the organisations that can trust, govern, and measure them, not just run them. Our go-to-market team is one instance of that. It is not the only one here, and it will not be the last one we write about.


