
How We Measure What AI Says About Us: An LLM Visibility Audit
We built a category once and could see ourselves winning. Building the next one, we couldn’t see the scoreboard.
The first category we built, we could see ourselves winning. Data observability didn’t exist as a market until we helped make it one, and the signs it was working were out in the open where we could count them: analyst coverage, search rankings, our own language turning up in other people’s decks.
Now we’re building a second category, agent trust. This time, when we went looking for those same signals, they weren’t there. The people forming opinions about us weren’t reading our site. They were asking an AI, and none of us could see what it was telling them.
So we ran one of the questions we assumed we’d win, something close to “best platforms for AI agent observability.” It came back as a clean list pulled from about nine sources, and we weren’t on it. We only showed up when the tool ran a second search for “Monte Carlo” by name and folded those results in. A buyer who asked the first question and stopped there would never have seen us.
There’s a real gap between what an AI says about you when someone asks by name and what it says when nobody does, and from where we stood we had no way to see it. So I built a way to measure it . We call it our “LLM Visibility Tool.” This is sometimes called generative engine optimization (GEO) or answer engine optimization (AEO). I’m using LLM visibility because this is about how to measure the gap.
How we measured LLM visibility
I gathered 25 prompts and grouped them into three kinds of buyer behavior: branded questions like “what does Monte Carlo do,” problem questions like “how do I monitor AI agents in production,” and comparison questions like “Monte Carlo vs. X.” I ran all 25 through six platforms: ChatGPT, Perplexity, Gemini, Grok, Claude, and Copilot. That came to 150 responses.
Scoring 150 answers by hand isn’t a real plan, so the tool runs on a rubric I built in Claude to keep it consistent: was Monte Carlo mentioned at all, was the positioning right, and where did we land against competitors. Every response went into Notion, row by row. Then I went back through the citations to see not just what each platform said, but which page it pulled the answer from.
I expected a content problem. We didn’t have one.
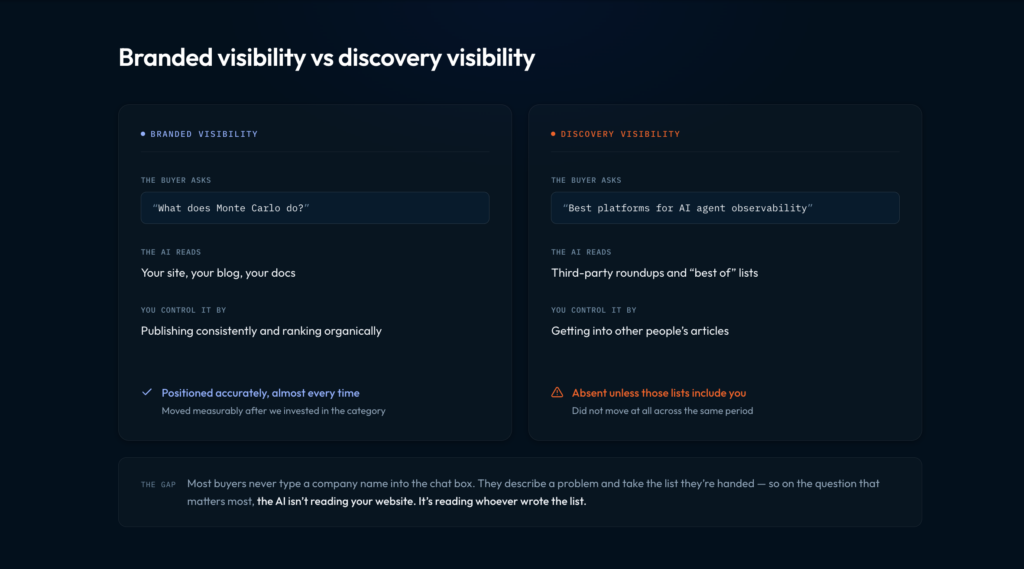
When someone asks about Monte Carlo by name, or asks a technical question our content already answers, we show up correctly almost every time. The AI has clearly read our blog and our docs, and it repeats our positioning back accurately. On those questions, it works.
The problem was somewhere else. On generic discovery questions, the kind someone asks before they have any vendor in mind, we almost disappeared. The citations showed why. For those answers the platforms weren’t pulling from us at all. They were pulling from a small set of third-party “best of” roundup articles and repeating what those articles said. None of our own pages were in that pool.
That distinction matters more than it sounds like it should. Most buyers never type a company name into the chat box. They describe a problem, ask which tools are best, and take the list they’re handed. On that question the AI isn’t reading your website. It’s reading whoever wrote the list, and treating that page as the truth.
Branded visibility vs. discovery visibility
I’ve started thinking about this as two separate kinds of visibility, not one:
— Branded visibility. Does the AI get you right when someone already knows your name?
— Discovery visibility. Does the AI recommend you when someone doesn’t?
For years, ranking well on Google covered both at once. Good SEO made you findable by name and by problem. AI platforms broke that link. They still find you by name, but for the discovery question the content in the middle, the reviews and comparisons and roundups, now counts for more than anything you’ve published yourself.
Then we tried to move it.
What moved after we went after the category
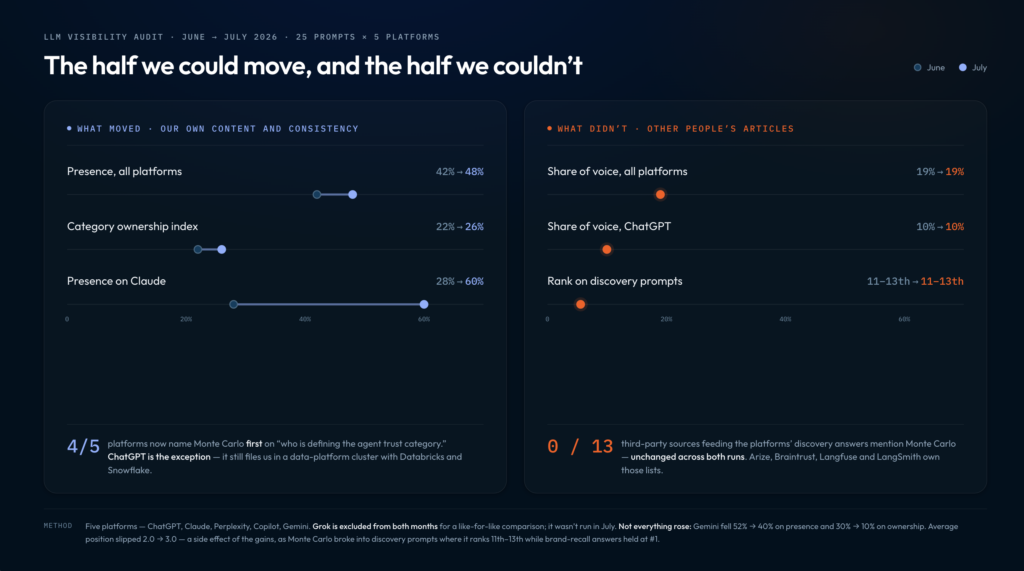
In the weeks after that first audit, we went to work on owning the category. We shipped a dedicated Agent Trust page, renamed and redesigned the blog around the category, and said the same thing about it consistently across every surface we control. We also earned a first-page organic ranking for “agent trust,” which matters because organic search is one of the signals these platforms lean on when they decide what to pull. Then I ran the whole battery again. Five platforms this time as we dropped Grok, which sends us no measurable referral traffic at all.
The branded and category side had moved. Platforms that used to file us under generic “data platforms” started naming us first when someone asked who’s defining agent trust. On one of them, how often we came up by name more than doubled.
I won’t claim our work alone did that. The models retrain, the web shifts, and I can’t cleanly separate what we did from everything else happening in the same stretch. But the direction was hard to miss. The more telling result was what didn’t move. We gained ground on how the platforms describe us and none at all on which lists they pull from. The part of our visibility that answers to our own content and consistency went up.
How to test your own discovery gap
You don’t need 150 scored answers to get a first read on your own gap. Pick three or four platforms your buyers actually use. Ask each one a branded question and a generic version of the same question, then ask for sources. If you come up cleanly when you’re named and disappear when you’re not, you have the same gap we did.
We tell customers this constantly: you can’t trust an AI system you haven’t observed. Watch what goes in, watch what comes out, and don’t assume the model is doing what you think it’s doing. That applies to how AI platforms describe your own company, not just to your production pipelines. We never stopped watching. What was worth watching changed, and our instruments were still pointed at the old surface.
So this isn’t a final state. We’ll keep changing how we measure LLM discoverability as the landscape itself keeps changing. But above all else we’ve focused on the tools our customers actually use. Everything we see says they’re using LLMs more than ever.


