
Production is Not a Bigger Dev: How Evals Leave Your Agents Unwatched

Every AI team that has shipped an agent has likely utilized a golden dataset evaluation; essentially a curated set of prompts with expected completions, a scoring harness, a threshold to clear before merge. Evals are very useful, as they let us take a highly unpredictable system and produce a scalar to gate a release on.
However, we can’t treat them as the finish line once we start deploying agents in production.
Golden-dataset evaluation is a development practice, and production is not a bigger version of development with more traffic and a higher rate limit. It is a categorically different environment with a different failure surface, and the properties that make an offline eval suite work before release are exactly the properties that no longer apply once an agent is out in the wild.
What makes an eval work before release
In dev, you control the prompt context, mock tool outputs, and user state. The trajectories it actually realizes, therefore, are a small, repeatable subset of the ones its code permits.
In production, autonomous agents run on non-deterministic LLMs interacting with live, volatile software and data environments.
Four things are true in development which do not apply in production:
- The input distribution is frozen. You chose this in dev, and it does not move unless you move it.
- A human has time to enumerate. An engineer sits down and writes out what could plausibly go wrong.
- The surface is bounded. You are examining one agent, one version, and one prompt set at a time.
- A human reads the result. A failing score has an owner who is actively looking at it.
Every one of those is a dev-time luxury. When you remove them, the same harness still executes and emits a number, but it covers far less of what can actually go wrong in production.
Why golden datasets don’t scale in production
You only catch what you thought to anticipate
Tools built for AI development—like offline test suites, static RAG evals, or offline LLM-as-a-judge frameworks—rely on a fundamental assumption: you can anticipate the step-by-step execution path.
This is a clear structural limitation of golden dataset evals: they are a record of anticipated failure. They are not evaluating autonomous decision-making in real time.
Production agents fail through “unknown unknowns” across complex execution graphs. Production is also the residual: all the failure patterns left over after you already fixed what you could anticipate going wrong in development. And that residual, unfortunately, can’t be enumerated in advance.
Pushing more coverage into dev shrinks the residual, but it does not remove the need for something watching production, because the residual is where the most complex failures emerge.

Engineering cost spiral as you grow your agent fleet
A golden dataset is not a fixed asset. It is a maintained artifact with an ongoing authoring cost, and that cost compounds across the number of agents your platform team supports, the number of prompt and model variants in flight, a retrieval corpus that turns over constantly, and expected completions that get stale every time an underlying document is revised.
Automating the execution of the suite is the obvious first move and it helps immediately. The harder problem is authoring. Engineering headcount does not grow at the rate that the agent surface does, which means production issue detection has to work without a pre-curated question set or it does not work at production scale.
Real traffic drifts away from your snapshot
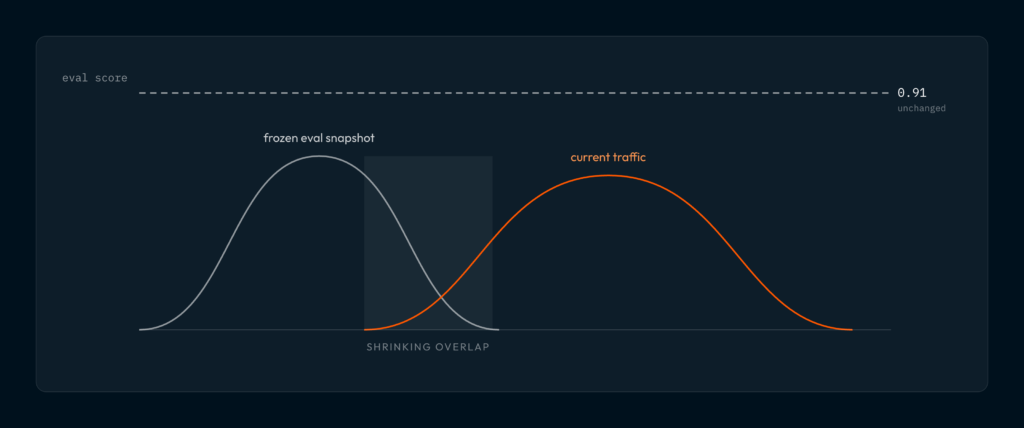
The distribution your agent actually serves stops resembling the one you froze. Users engage with your agent with phrasing and terminology that could not be anticipated during dev testing, while seasonality shifts the topic mix, and new integrations put a different class of request in front of the same agent.
Changing factors like these mean that your scoring system now reflects a distribution that no longer exists. That is what makes this dangerous: nothing looks “wrong” with the agent’s output because the grading system isn’t calibrated for the current reality anymore.
The deeper problem: evals only score an output
The scaling limits are one half of the argument; the other is about what an eval actually measures.
An eval takes an agent’s completed output and scores it. This is important, as output quality is a real pillar of agent trust and it needs continuous scoring. But a large share of production agent failures are not identifiable by simply looking at the output. They are failures of trajectory, of performance, of context, and of structural invariants. Take the following failure types, for example. When looking only at evals, each might return a 200, a normal latency, and a plausible-looking answer, leading your engineering team to ignore real performance risks.
- Unbounded state and tool cascades. An internal API or database returns an unexpected schema or a 503. Rather than failing cleanly, the agent attempts to self-correct — hallucinating subsequent tool arguments and entering a runaway multi-turn loop. It converges eventually and returns something reasonable. The completion scores fine, while the token spend on that trace is an order of magnitude above the median.
- Tool argument misalignment. The model emits arguments that are structurally acceptable to the target endpoint but semantically wrong — right shape, wrong filter value or entity id. The call succeeds and returns a real, incorrect result set, which the agent then reasons over in good faith.
- Silent empty returns. An upstream service returns an empty result set instead of an error. The agent dutifully summarizes this nothingness into a confident, generic paragraph. Fluent, well-formed, and content-free.
- Compound error amplification. A minor hallucination at step two of an eight-step chain propagates through every subsequent step’s reasoning. For an acting agent, that means irreversible side effects committed on faulty intermediate state: a write executed, a ticket filed, or even a payment moved. The final completion often looks entirely reasonable, and by the time anything surfaces, the side effects are committed. The failure is in the trajectory, not the answer.
- Goal drift under context pressure. As a session accumulates tool responses and retrieved chunks, the context window fills with content that is mostly low-relevance to the current step. Model performance does not hold flat as input length grows: Chroma’s evaluation of 18 frontier models — GPT-4.1, Claude 4, Gemini 2.5 and Qwen3 among them — found accuracy degrading non-uniformly with input length, with distractor content in the window as one of the factors driving it. The practical consequence is goal drift: the agent works through a multi-step task and stops pursuing the objective it started on. It still returns something well-formed, but it is answering a different question.
- Non-terminating reasoning loops.
Thought → Action → Failure → Thought, cycling until the token budget is exhausted with no final response returned. The agent is genuinely reacting to each failed observation; what is missing is a termination condition that fires. In a multi-agent graph this can occur between agents rather than within one, in which case no individual agent’s trace or output looks pathological. - Silent model substitution. A dependency bump moves the agent onto a different model than the one you evaluated and approved. Latency, cost, and refusal behavior shift. No test in your eval suite can identify which model actually ran.
- Asynchronous infrastructure jitter. A vector store times out, a rate limiter throttles, or a provider has a latency spike. Retrieval returns partial or truncated context and the agent answers confidently from whatever arrived.
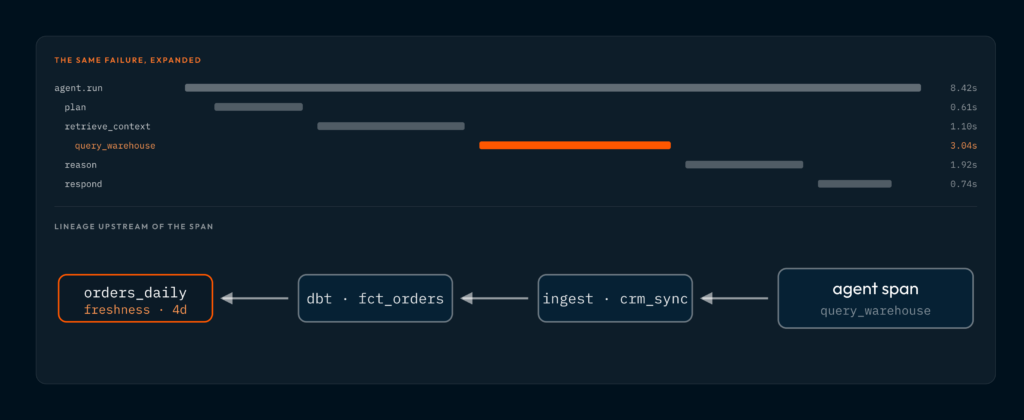
- Stale context. The agent reads a warehouse table that stopped refreshing days ago and produces a well-formed, internally consistent, entirely wrong answer about last week’s numbers. This is the worst one, because the agent did everything right and the failure is many steps upstream.
An output scorer can’t see any of these types of failures, which occur at various points in the agentic stack; and it simply cannot be expected to.
Output scoring covers one of four pillars that make up agent trust
We frame agent trust as four pillars. Consider the question each pillar answers when investigating and optimizing an agent, as well as how silent failures happen in these pillars and what steps can actually be taken to catch them:
| Pillar | The question it answers | How it fails silently | What actually catches it |
|---|---|---|---|
| Context | Is the data feeding this agent correct? | Stale table, unannounced schema change, late pipeline; the answer is fluent, but the facts are wrong. | Data monitors and prompt-based evaluations on the tables the agent reads, upstream of the agent. For retrieval-backed agents: output evaluations scoring faithfulness to what was actually retrieved. |
| Performance | Is it fast, reliable, and affordable? | Latency creep under real concurrency, and cost variance that offline testing cannot produce: one user prompt might trigger two tool calls or thirty | Metric monitors — latency percentiles, anomalous token spend, error rates, request volume |
| Behavior | Did it follow the right steps? | Skipped step, wrong sequence, unexpected step counts, non-terminating loop — correct-looking result | Trajectory monitors — expected tool-call sequence and frequency. Note that goal drift is the exception here; it needs an output evaluation scoring relevance against the original request. |
| Output | Is the completion any good? | This is visible with evals | Evaluation monitors — LLM-as-judge and deterministic checks, running continuously against live traffic |
| Bonus: Structural guardrails | Did this trace violate a rule you can state up front? | Silent model substitution, a token ceiling breached on individual traces, a duration limit blown | Validation monitors — pass/fail assertions on trace fields: which model ran, token ceilings, duration limits |
The four pillars constitute the trust stack; structural guardrails are the deterministic assertions that cut across all of it. A model substitution, for example, would land here. It is not an output problem, a latency problem, or a sequence problem, but rather a rule you can state in one sentence and assert on every trace.
Golden-dataset evaluation is captured in the Output row. As you can see, it is an essential part of the stack, but it’s not the entirety of trust infrastructure by any means; a platform whose whole monitoring strategy is to score the completion is only covering one pillar of four.
Scoring is not troubleshooting
Suppose your output scores do degrade and you catch it. What do you actually know about the failure?
It turns out, not enough to adequately troubleshoot the issue.
That’s because a score is a scalar; it carries no trace, span timings, tool-call sequence, record of which model executed, or link to the underlying data the agent read. So the investigation starts from zero. An engineer must pull traces by hand, guess at a window, connect with the data team to see if anything shifted upstream, and wait. The MTTR is upwards of multiple hours.
Two things make this materially harder in production than in development:
The first is topology. Production agent systems run on distributed state stores, vector databases, and multi-agent delegation patterns, orchestrator-worker being the common one. Dev debugging, however, typically inspects a single execution trace. Root-causing a production failure means replicating the whole path: the tool calls, the retrieval lookups and the handoffs between agents, in order, with timings. Anything less and you lose the ability to truly isolate the one variable that threw off the whole system.
The second is that agents fail because of their context as often as their logic. For a warehouse-grounded agent — text-to-SQL, Snowflake Cortex, Databricks Genie, and anything else reading your tables — the likeliest single root cause of a bad answer sits upstream of the agent entirely. If your agent observability does not know your tables exist, every output you evaluate downstream will only report the symptom of a failure that has its origin in the data layer.
Two questions to check yourself
Of course, you don’t have to take our word for it that evals are insufficient in production, you can check for yourself. To do this, take your last real agent incident and walk it backwards.
How did you find out about the incident? Was it from a tool monitoring your agent, or from a human? If a human noticed first, the failure was outside your test set. Writing a test for it now protects you against that exact failure, but does nothing for the rest of the unknowns that exist in production.
Once you knew about this failure, how long until you could identify the root cause? If the answer is measured in hours, and if most of those hours went to pulling traces and asking whether anything changed upstream, you do not have a detection problem – you have a troubleshooting problem. Your evals are doing the work at the end of the stack, but the 3 other layers are a major blind spot.
How Monte Carlo approaches it
Monte Carlo runs four monitor types against live production traces, one per pillar.
Evaluation monitors score output quality continuously at production scale — LLM-as-judge, deterministic code-based checks, or low-code templates — and run asynchronously, so they never block an agent response.
Metric monitors track latency percentiles, token consumption, error rates and request volume, which is where cost variance and performance regressions surface.
Trajectory monitors assert expected execution paths: that one span precedes another, that a step does not repeat more than N times, that a required check runs before a write.
Validation monitors enforce per-trace constraints — which model ran, a token ceiling, a duration limit — and are what catch a silent model substitution. Underneath all four, data monitors and context evaluations cover the tables the agent reads.
For low-volume agents, we recommend starting with deterministic validation rules and code-based evaluations, which hold true or false regardless of sample size. As agents scale and volume supports building a baseline, you can overlay anomaly detection on top of your monitors.
Because the platform unifies the data and agent layers, an active data quality incident on an upstream table surfaces directly on the agent’s own page via a lineage view. You can connect the dots without needing to cobble together separate tools.
Necessary, but insufficient
Pre-release evaluation is an essential part of building reliable agents. It catches regressions before users see them, creates a defensible release bar, and gives AI engineers a way to reason about whether a prompt change helped. It gives us confidence that what we are pushing to production is sound.
But stopping there leaves us blind to the real-world conditions that our agents will be operating in. Production requires continuous coverage across all four pillars, detection that does not depend on a pre-curated question set, and root-cause analysis that reaches back into the data.
To learn more about how Monte Carlo can help your engineering team achieve full coverage in production so you can confidently scale your agents, get in touch.


