
Building autonomous agent trust: RL, an agent fleet, and comprehensive observability
For many organizations, getting agents to successfully run in production, particularly to the extent that they can be trusted to be completely autonomous, seems like an insurmountable challenge.
Agents look great in pilots, but once they are deployed live, issues inevitably emerge. Production is unpredictable; agents have to operate in conditions that cannot be anticipated and make decisions with variables that they were not trained on.
But what if your agents could learn from their failures in production and actually get better and better?
This idea, that agents can improve autonomously — detect their own failures, fix them, and get better without a human operator – sounds like science fiction. It isn’t. We’re closer to that self-optimizing future than most people think, and what it takes to get there might surprise you because it’s something we’ve already built: trust infrastructure.
In my session at Ai4 this past week, I introduced a framework for how enterprise teams can enable their agents to self-optimize. I also talked about how we’re doing exactly that at Monte Carlo with our Agent Trust platform.
Self-improvement is infrastructure, not an “on” switch
It’s tempting to think of self-improvement for AI agents as reliant on the model. As the models get more and more advanced, surely our agents simply get “smarter” and more adept over time? While model improvement certainly makes a difference, it is only one small piece of what it takes to build a trustworthy agent. There is no switch we can flip to make an agent improve itself.
Rather, agentic self-improvement is more like infrastructure; you have to build it into your architecture deliberately.
There are three parts to this infrastructure:
- A blueprint. What is the repeatable algorithm that shows us how to optimize?
- Labor. Someone has to execute that algorithm, over and over, at scale. Who does it?
- A foundation. What signals do we feed the algorithm so that what it optimizes toward is actually true?
The blueprint: a reinforcement loop
Most data and AI practitioners are familiar with reinforcement learning. It has a clear shape: an agent observes a state, takes an action, gets a reward, and updates its policy. Run that loop enough times against a good signal and performance improves. That part is well understood.
The algorithm isn’t the hard part. The environment is. You need something that can produce different states and rewards, cheaply, at volume.
Here’s the insight that changed how we think about this: if you run agents in production, you already have the environment. Your production system generates a reward signal all day long. You just aren’t using it as one.
Think about all the data you already have when an agent operates in production:
- Traces — every tool call, model invocation, error, and retry
- Evals — continuous benchmark scores from grading outputs
- Operational context — filed tickets, merged PRs, resolved incidents
You already have three streams of signal, running constantly.
The problem is that nothing connects them. Each one gives you a partial, disjointed picture of what your agent is doing. Even when you can see that something is off in one of them, there’s no path from noticing that something is wrong to truly understanding the root cause and implementing the fix.
Engineers must sift through traces and evals, and the work required to actually move from detection to improvement is extremely manual and often siloed across different teams.

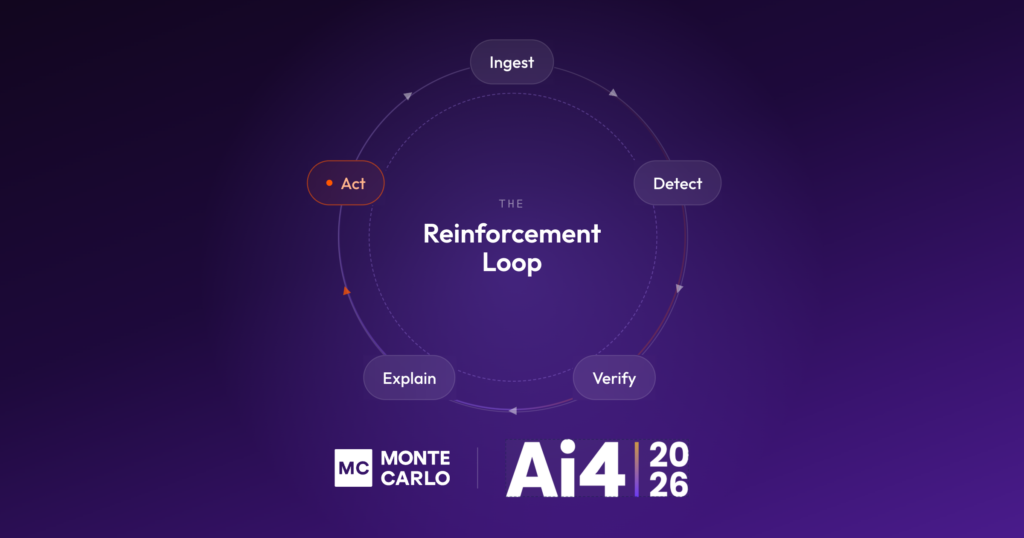
What we need is to unify those signals in a shape that follows the principles of reinforcement learning. At Monte Carlo, we call that the Reinforcement Loop.
This is our proposal for how the path of taking in signals, evaluating those signals, and learning from them to ultimately improve looks:
Step 1: Ingest. Take all of it — traces, evals, your PRs — and consolidate them.
Step 2: Detect. Now find the failures that, without a consolidated system, might look “normal”. This is where connecting the signals pays off because you can correlate them to reveal hidden issues. Here is a concrete example: say your agent gives two different answers to two different users. It passes the eval, because both answers are anchored in real data — they just came from two different tables. Nothing looks wrong, but when you look at the traces alongside the evals, it becomes obvious that two different answers to the same question, drawing from different sources, is not acceptable. No single signal catches that independently, but together they do. And notably, the detectors doing this work are deterministic; you want the thing finding failures to be boring and repeatable, not creative.
Step 3: Verify. Once the hard step of detecting the issue is done, we have to confirm: is this real, and has it already been fixed? This is where your operational context earns its keep. You can check the pull requests related to the issue and confirm whether a fix has already landed, or whether the thing you found is genuinely open. It’s the difference between a system that files useful work and one that files noise.
Step 4: Explain. Outline the root cause and the fix, with cited evidence. We are way past saying “this trace looks anomalous.” The system must provide the actual reason and what to do about it.
Step 5: Act. A ticket, a draft PR, a new monitor. Here is the part that makes it a true loop: the system must be able to specify what action to take and enable the engineer to do it with a single click (or, in the near future, take that action on its own). In this way, today’s fix becomes tomorrow’s input. Once that PR merges, that new state is the baseline and the next cycle runs from a better starting point, and the cycle after that runs against a better one still. Your production environment is the environment for the reinforcement loop.

The labor: an agentic fleet
The loop, then, is our blueprint, and it’s easy to see how it can work for a manageable number of agents with engineers running each stage.
But what happens, for example, when you have 100,000 agents?
Many teams stall out when trying to scale because they cannot manage a reinforcement loop with humans. Every station in that loop is a place where a human currently sits. An engineer notices the issue, sets up the monitoring, troubleshoots, triages, writes the fix, writes the tests, and files the ticket.
We need to evolve from that system if we have any hope of running self-optimization at scale, and that is where an agentic fleet comes in.
The first four steps of the loop — detect, prioritize, diagnose, recommend — can run autonomously. The last ones, validate and deploy, are where the human belongs. Before the fix ships, a person reviews it and clicks approve. Given where we are today, I think that’s a very important component, and I’m not in a hurry to remove it.
The way to achieve this is by building each station of the loop as an agent in its own right. Monitoring, triage, troubleshooting, remediation, compliance, cost — a fleet that runs the loop 24/7 and doesn’t need to take a break. That’s how you increase the labor available to you without increasing headcount, and in our experience it’s what lets the loop hold up at real volume.
The foundation: cohesive observability
None of this works without a strong foundation in place to ensure all of the signals are complete and unified. That foundation is a cohesive, end-to-end observability solution running underneath the whole engine.
That’s because, if you look at each signal in isolation, you will reach the wrong conclusion.

Telemetry alone, for example, shows you the agent but not the context underneath it, while evals alone give you a score but not the behavior that produced it. Without a connection to the actual code or PRs, you have no grounding — you can’t tell what’s real from what someone fixed last sprint.
The failure mode, in this case, is worse than just a single missed incident. Your agent can actually learn the wrong patterns, submit the wrong fixes, and reinforce its own bad behavior. This behavior then compounds; the agent gets worse in a way that looks better.
The instinct to consider evals or traces on their own as “good enough” is a core mistake. You need visibility across all the components of the agentic stack. You can think of that across these four dimensions:
Context. Is the data the agent is drawing from correct? Freshness, volume, schema – the bread and butter of data engineering. The hard part is doing it across all the data your agents can reach, at scale.
Performance. Are the agent’s runs slow, costly, or broken? If your agent takes four minutes to answer, your customers will not tolerate that. If a single agent run costs hundreds of dollars, that’s probably not something you want to do at volume — or at least not without knowing. Latency and cost are trust problems, not just infrastructure problems.
Behavior. Is the agent calling the right tools, in the right order? Dashboards were wrong sometimes too, but agents are wrong with confidence. Agents reason and make decisions, so you need to be able to trace the series of decisions they made.
Outputs. Are the final results fit for use? Context, performance, and behavior can all be perfect and the answer can still be wrong for the question. Perhaps it’s too long, too short, impolite, unhelpful, or recommends your competitor four out of five times.

Here’s the catch: this is very hard to do in an enterprise environment, because enterprise environments are heterogeneous and getting more so.
Organizations are using multiple models, each chosen for cost and capability, with multiple agent frameworks for flexibility. They are drawing from many context sources, different telemetry stacks, and using different ticketing systems.
That heterogeneity doesn’t change the four core elements of the agentic stack that require visibility. It just means that having true end-to-end visibility across all of it is more critical than ever; it’s ultimately what makes the reinforcement loop trustworthy enough to act on.
What I think happens next
When it comes to the future of agentic AI, the question around whether models are capable enough is rapidly closing, and the one replacing it is more vague: how would you even know?
Capability is a property of the model, and you can buy it. Verifiability is a property of your system, and you have to build it. As enterprises figure out how to quickly and cheaply validate an agent’s output, that will give them operating leverage and competitive advantage. Ultimately, that’s what lets you take more and more steps back as a human. We’re moving from operator to overseer, to ultimately goal-setter. And, every time we automate a rung, the scarce skill becomes the one just above it.
Right now it’s reviewing agent work, but soon it’ll be deciding what the agents should be working on at all.
Adapted from my talk at Ai4 2026.
Barr Moses is co-founder and CEO of Monte Carlo.


