
Agent Trust
AI Observability
Five Failure Modes Evals Won’t Catch and What to Do About Them
Evals are a critical part of every data and AI team’s agent development process. An engineer builds an eval, defines what a bad answer looks like, runs a judge against a test set, and ships when the score looks good. When the initial hypothesis is correct, evals work as designed. But when an agent fails …
Agent Trust
Fine Tuning vs. Training a Model
Training builds a model from scratch; fine tuning adapts one you already have. See the tradeoffs in cost, data, and results.
Agent Trust
How to Stop Prompt Drift From Wrecking Your AI Outputs
Nothing changed in your prompt, but your outputs did. Learn how to spot the warning signs early and stop bad data from spreading downstream.
AI Observability
Catching the Bug That Never Throws an Exception
There is a certain type of failure mode that keeps platform teams awake. Take, for example, this scenario that a platform engineering team in the insurance sector might face: A release goes out. Somewhere in a mapping layer, however, a field stops flowing, resulting in “driving conviction” dropping out of the quote request unnoticed. No …
Agent Trust
Agent Trust in 2 Weeks: Part 4, Your first alert fired
At the end of Part 3, your monitors were live and routed, and we said something was going to fire. Well, something just did. Maybe it came in as a Slack message or an email, or maybe a new row at the top of the alerts feed. Before you go heads-down and start debugging, let’s …
Agent Trust
Agent Trust in 2 Weeks: Part 3, Traces are flowing. Now what?
In Part 2 of this four-part series, we worked out what’s worth monitoring on your particular agent, and in what order. At this point, the traces are arriving in Monte Carlo. You can already do more than just watch them flow in. You can open any conversation, run an evaluation on it, and get a …
AI Observability
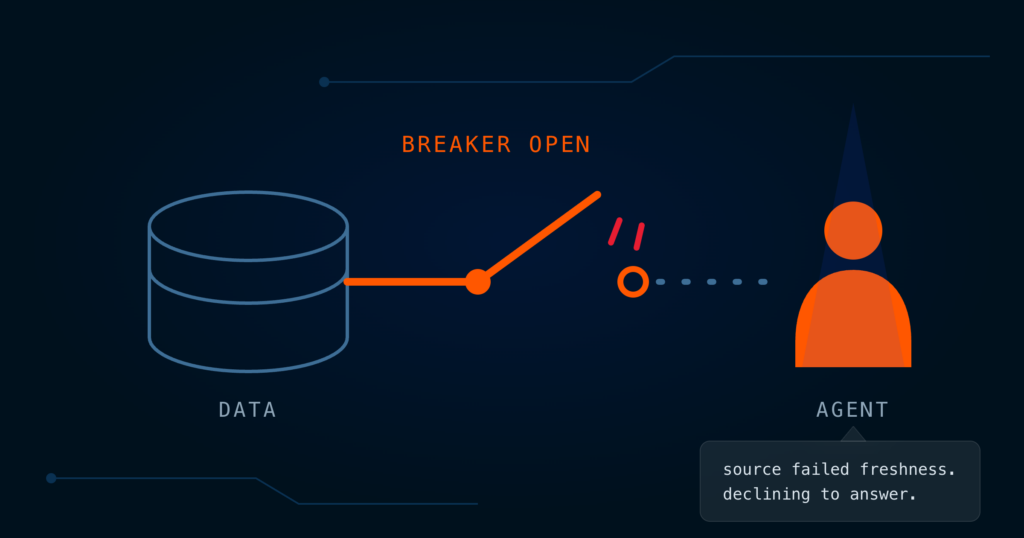
Circuit Breakers for Agents: Driving Agent Trust with Monte Carlo
Four years ago, Monte Carlo shipped circuit breakers to stop broken pipelines before bad data hit a dashboard. In 2026, the same idea has a new job: stopping an agent before it turns bad data into a confident answer. In electrical engineering, a circuit breaker exists because prevention beats detection. You do not want an …

AI Observability
Token prices are falling, so why is your AI bill going up?
There’s a clear narrative sweeping the software world these days: AI is getting dramatically cheaper. Or, to be more specific, inference is getting cheaper. Various researchers have been quantifying this: Stanford’s AI Index, for example, tracked the cost of querying a GPT-3.5-equivalent model falling from $20.00 per million tokens in late 2022 to $0.07 by …

Agent Trust
How Monte Carlo’s Reinforcement Loop Caught a Silent Issue in Our Own Troubleshooting Agent
Inside the Monte Carlo platform, our Troubleshooting Agent (TSA) works behind the scenes to analyze data and AI incidents, pinpointing root causes and suggesting fixes in real time. To keep TSA—and our other production agents—running efficiently, we rely on the Reinforcement Loop, an automated monitoring system designed to continuously evaluate agent performance, catch subtle inefficiencies, …
Read more related stories
Data Observability
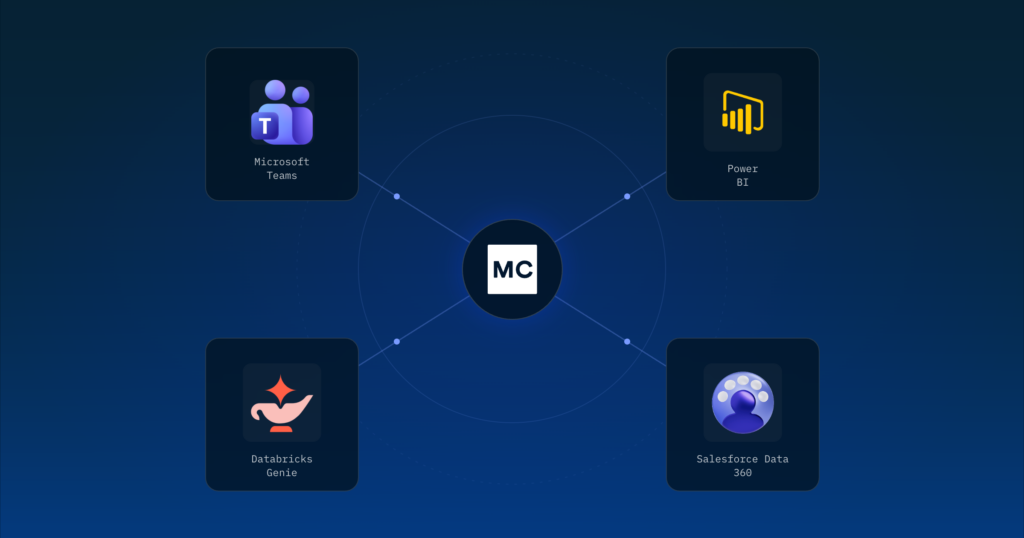
Our latest integrations embed Monte Carlo further into your data and AI ecosystem
Enterprise data stacks don’t converge on one cloud or one vendor, and they aren’t going to. A customer might run analytics in Databricks, push audiences out of Salesforce, alert in Microsoft Teams, and debug agents in Claude, all in the same week. Monte Carlo has to meet the data and the agents wherever they already …
Data Observability
Describe your orchestrator to Claude, get a real integration
ETL and orchestration is one of the most varied integration categories our customers ask for. Alongside the mainstream tools we cover natively (Airflow, dbt, Fivetran, Azure Data Factory, and more), enterprises run dozens of others: commercial platforms, cloud-native services, and homegrown schedulers. Every one of them runs pipelines that feed what’s downstream: the warehouse, the …
AI Observability
How AI Anomaly Detection Catches the Problems Your Tests Miss
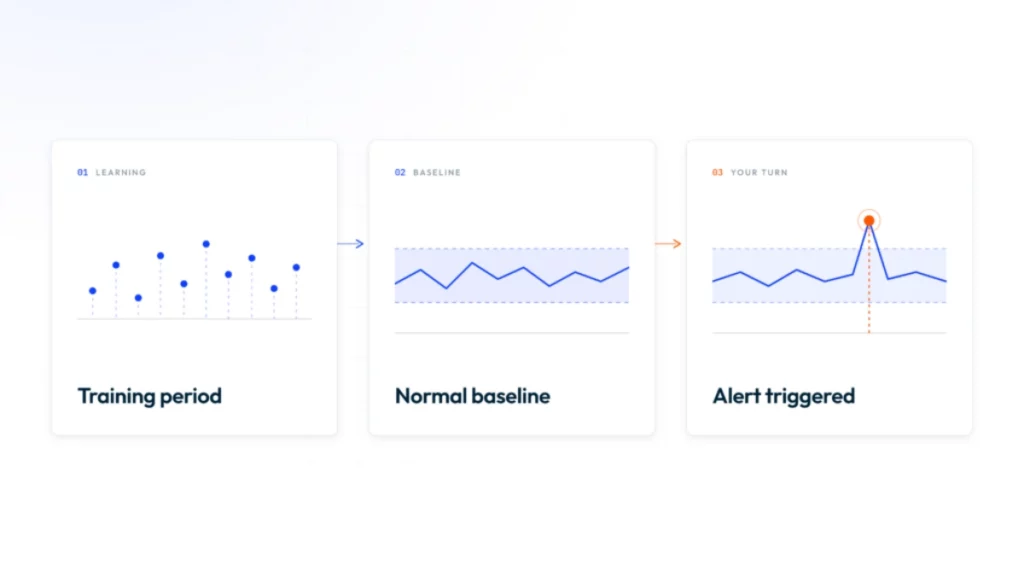
Every table you monitor has a rhythm. Here's how AI learns it, what happens when that rhythm shifts, and how to build a detector that keeps up.

AI Observability
The 18 Best AI Observability Tools in Sep 2026
Whether you're monitoring a handful of models or managing AI at enterprise scale, you need AI observability tools. Let's dive into it.
AI Observability
The Open vs. Closed AI Debate Misses the Point: Most Orgs Cannot Measure Either
The discussion around enterprise AI often focuses on the choice between open-weight models, like Meta’s Llama and models from Mistral, vs. closed frontier models, such as Anthropic’s Claude and OpenAI’s GPT models. While closed frontier models promise state-of-the-art reasoning without managing infrastructure, open-weight models promise sovereignty, portability, and freedom from vendor lock-in. Public commentary has …

AI Observability
LLM Evals: What They Are and How to Get Started
TL;DR: Imagine hiring someone for a critical role, letting them start the job, and never once checking their work. Most companies would never operate this way with a human employee, yet that’s effectively how a lot of teams have shipped their first LLM-powered features. They build, deploy, and hope for the best. As enterprises have …