
AI Culture

AI Observability
Token prices are falling, so why is your AI bill going up?
There’s a clear narrative sweeping the software world these days: AI is getting dramatically cheaper. Or, to be more specific, inference is getting cheaper. Various researchers have been quantifying this: Stanford’s AI Index, for example, tracked the cost of querying a GPT-3.5-equivalent model falling from $20.00 per million tokens in late 2022 to $0.07 by …
Agent Trust
The EU AI Act: Are You Prepared for What’s Next?
Given the plethora of LinkedIn posts on the subject, if you deploy a general purpose agent or other AI system to the EU market, you are likely aware that the majority of EU AI Act Article 50 transparency rules went into effect on 2 August 2026. At a high level, Article 50 requires providers and …
AI Culture
Inside Monte Carlo’s GTM Hub: How We Run our Revenue Team on AI Agents
With the proliferation of AI across businesses for internal use cases, teams are quickly spinning up agents to take on many of the tasks that humans used to do. With that inevitably comes some operational chaos. Walk into almost any go-to-market org today, for example, and you will find the same thing we found when …
AI Culture
What Is an AI Observability Engineer? 5 Key Skills, Responsibilities, & Tools
Quick Answer An AI observability engineer monitors, troubleshoots, and improves the reliability of AI systems in production including the data pipelines, models, and agents involved in the stack. Where a data engineer builds pipelines and an AI/ML engineer builds models, the AI observability engineer makes sure both keep working as intended once they ship. As …
Agent Trust
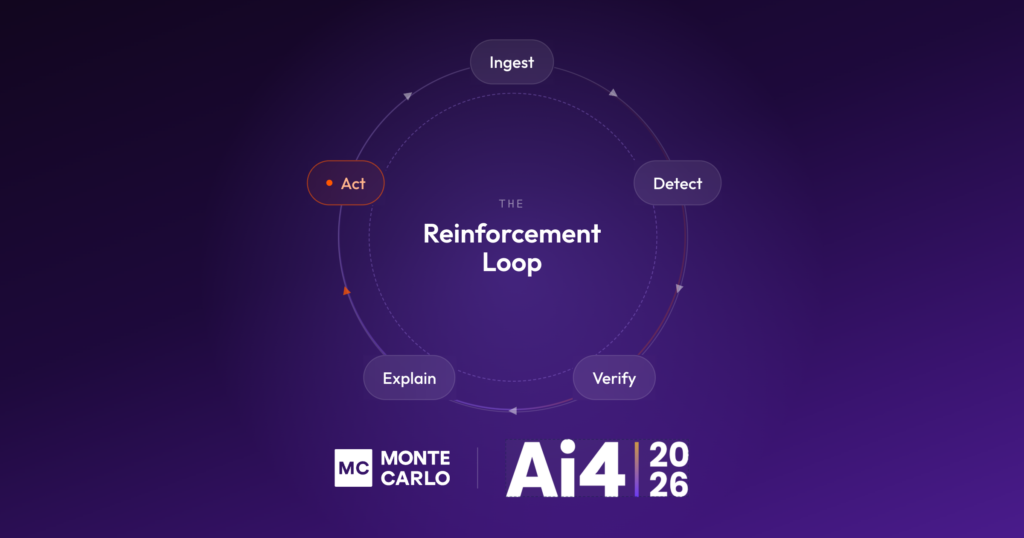
Building autonomous agent trust: RL, an agent fleet, and comprehensive observability
For many organizations, getting agents to successfully run in production, particularly to the extent that they can be trusted to be completely autonomous, seems like an insurmountable challenge. Agents look great in pilots, but once they are deployed live, issues inevitably emerge. Production is unpredictable; agents have to operate in conditions that cannot be anticipated …
AI Culture
Monte Carlo’s Enterprise Platform Updates: Coverage and Control Below the Agent Layer
Our enterprise customers are shipping agents in production at scale, and that raises the bar on everything underneath them. An agent is only as reliable as the data it reads and the guardrails on what it’s allowed to do with it. That’s why we continue to strengthen and expand the capabilities of our platform. Read …

AI Culture
Nineteen security agents, one findings folder: how we AI-fied our security program
In November 2025, I turned our security architecture reviews into a repeatable workflow. That’s the whole origin story. No mandate came down to build an agent fleet. I got tired of running the same design review by hand and wrote a workflow for it instead. By February, the same instinct hit vulnerability triage. That workflow …

AI Culture
How to build an AI native engineering org: what we actually did
In March we restructured Monte Carlo’s engineering organization. As I’ve thought about sharing our decision-making process, I’ve wanted to be far enough past the restructure to say something honest, objective, and which other engineering leaders can hopefully find useful. The short version is that our teams and operating principles weren’t broken, which made it particularly …
AI Culture
Working smarter with Claude: a practitioner’s guide to token efficiency and output quality
At Monte Carlo, we run a lot of our workflows and processes on AI. Claude is woven into our product, our internal tooling, our agents, and our day-to-day tasks. So when I say teams are routinely wasting 30-40% of their token budget, I’m not guessing. This is something I’ve watched happen at scale, including inside …
Read more related stories
Data Observability
Our latest integrations embed Monte Carlo further into your data and AI ecosystem
Enterprise data stacks don’t converge on one cloud or one vendor, and they aren’t going to. A customer might run analytics in Databricks, push audiences out of Salesforce, alert in Microsoft Teams, and debug agents in Claude, all in the same week. Monte Carlo has to meet the data and the agents wherever they already …
AI Observability
Five Failure Modes Evals Won’t Catch and What to Do About Them
Evals are a critical part of every data and AI team’s agent development process. An engineer builds an eval, defines what a bad answer looks like, runs a judge against a test set, and ships when the score looks good. When the initial hypothesis is correct, evals work as designed. But when an agent fails …
Agent Trust
Fine Tuning vs. Training a Model
Training builds a model from scratch; fine tuning adapts one you already have. See the tradeoffs in cost, data, and results.
Agent Trust
How to Stop Prompt Drift From Wrecking Your AI Outputs
Nothing changed in your prompt, but your outputs did. Learn how to spot the warning signs early and stop bad data from spreading downstream.
AI Observability
Catching the Bug That Never Throws an Exception
There is a certain type of failure mode that keeps platform teams awake. Take, for example, this scenario that a platform engineering team in the insurance sector might face: A release goes out. Somewhere in a mapping layer, however, a field stops flowing, resulting in “driving conviction” dropping out of the quote request unnoticed. No …
Agent Trust
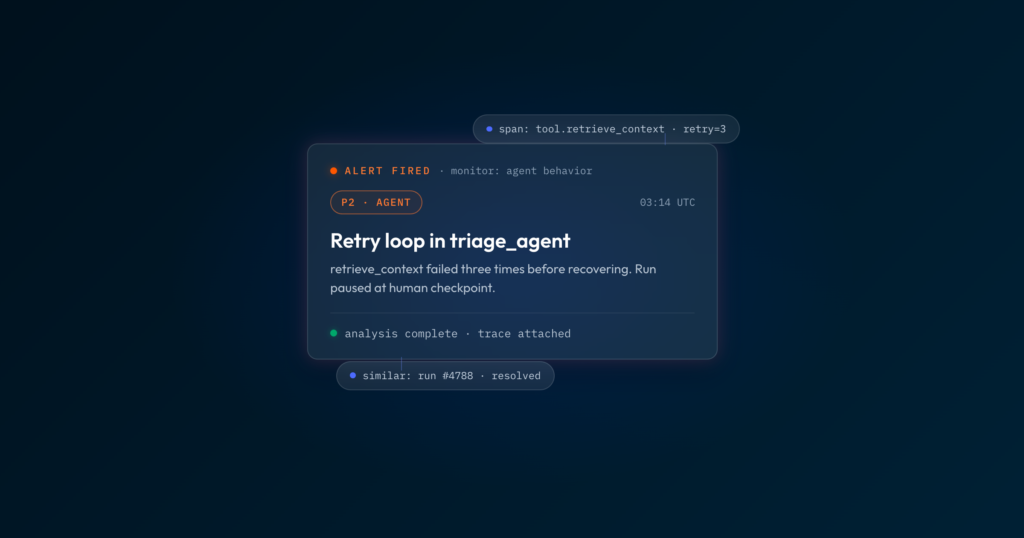
Agent Trust in 2 Weeks: Part 4, Your first alert fired
At the end of Part 3, your monitors were live and routed, and we said something was going to fire. Well, something just did. Maybe it came in as a Slack message or an email, or maybe a new row at the top of the alerts feed. Before you go heads-down and start debugging, let’s …