
Agentic Onboarding for faster coverage at scale
Onboarding has long been a manual, time-consuming task for engineering teams setting up data and AI observability tooling. That’s now a thing of the past with Monte Carlo. Agents read your estate, propose a monitoring strategy, and deploy it automatically the moment you approve. Full coverage happens in days, not months.
From connection to production coverage
Less manual setup work
More incidents caught vs. manual rules
Agents know what to monitor
They rank your data and AI assets by criticality, deep-dive into the ones that matter, and explain every monitoring recommendation in plain language.
Human-in-the-loop checkpoints
Nothing deploys until you approve it. You can enable the full plan that’s been recommended, choose a coverage group, or even choose just a single monitor. Plus, you are free to change your mind any time.
Coverage grows and evolves with you
New assets get covered, noisy monitors get tuned against the statuses your team sets, and gaps surface early on before they affect downstream business users.
Manual onboarding lacks context, resulting in incomplete coverage
Agents and their underlying data infrastructure are incredibly complex, producing an enormous amount of telemetry that requires a well-informed monitoring strategy to make sense of it all.
In the old world, engineers would set up a new tool by configure monitoring on a few critical agent metrics, like token usage or average latency per run, plus the most critical data tables or pipelines. After this initial push, the rollout typically stalls.
It’s not for lack of trying, but rather for lack of context. No individual, or even any central team, can possibly know which tables out of 2,000 actually matter to the business, what "good" looks like for each one, or which failures truly impact revenue.
Agents have more context than humans ever could
Monte Carlo's agents carry patterns learned across hundreds of deployments: which monitor types fit which asset profiles, which coverage gaps cause the most downstream pain, and which thresholds reduce alerting noise while still flagging real issues.
Agentic onboarding applies this intelligence to your environment specifically. The agents parse through your unique ecosystem, tracing lineage, learning query patterns, identifying downstream consumers of data products, and understanding business context.
Onboarding and monitoring powered by a fleet of agents
Agentic onboarding is made possible by Monte Carlo's specialized platform agents, which work as a coordinated fleet to seamlessly execute tasks and resolve issues across your data & AI ecosystem.
Troubleshooting
Automated root cause analysis the moment something breaks — hundreds of hypotheses per alert.
Triage
Sorts up to 50 alerts by confidence and impact, assigns owners, and suggests next steps.
PR Agent
Posts a weighted risk assessment on every PR — shift-left detection before code ships.
Monitoring
Finds coverage gaps across the warehouse and the agents acting on it — recommends the right monitor per table.
Cost
Identifies wasteful tables and verifies lineage before recommending removal, so cleanups stay safe.
Performance
Optimizes runtime and cost of pipelines — cross-referenced with downstream importance.
Observability
A natural-language interface to the full platform — Assist, Troubleshoot, and Support modes.
PII / Compliance
Describe what to protect in plain language; the agent maps it to columns and sets up monitors.
Agent Toolkit
Everything in the Monte Carlo UI, exposed to Claude, Cursor, and other AI agents. Apache-2.0.
Every step runs from the Monte Carlo UI or any MCP client — Cursor, Claude, Copilot — so your team works where it already is.
Works across your diverse data and AI stack
Monte Carlo supports the heterogeneous data and agent ecosystems that enterprises rely on, so you can take advantage of Agentic Onboarding without having to change anything about your existing stack.
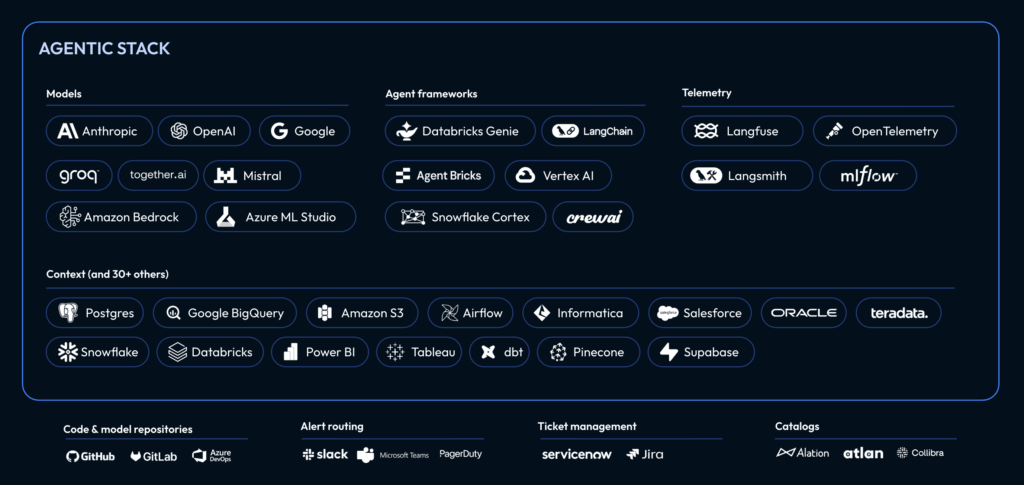
Native support for the platforms you’re running on
Seamlessly connect to Snowflake, Databricks, AWS, and 50+ more. Monte Carlo works from metadata, metrics, and query logs, never full copies of your tables. Field-level lineage across Snowflake, BigQuery, Redshift, and Databricks resolves to the column, and Cortex and Genie agent traces are read through the connection you already have.
One platform to connect data and AI
Monitor agents alongside the pipelines and tables that feed them, so you can see data incidents and agent incidents in one platform instead of two.
OpenTelemetry means no vendor lock-in
Instrument any agent on any platform. Monte Carlo ingests traces via the open OpenTelemetry standard, so switching frameworks or models doesn't cost you your monitoring.
Your environment, your rules
Agent telemetry stays in your own cloud account, deployed and controlled by you. Security, compliance, and residency stay where they already are. Deploy as fully managed SaaS, SaaS with a customer-hosted data store, or fully hybrid.
How Monte Carlo customers are onboarding, monitoring and ensuring agent trust faster than ever
Our 400+ leading enterprise customers are accelerating their time to agent trust using Monte Carlos agentic monitoring
Of all monitoring is agent-deployed
Major global retailer — 0 to comprehensive monitoring in 30 days
To steady-state coverage
Global media brand — full operational rigor on alerts
From plan to production
Leading beverage distributor — monitoring setup for a critical business domain
More real incidents detected
Global bank — and 87% fewer false positives with Monte Carlo agentic operations vs. in-house
See it across your own data and agent stack
Bring one domain. We'll show you the monitoring plan the agents propose for it, and what the first 30 days would look like for your team.
Trusted by 400+ enterprises




Common questions
How is this different from the APM and infrastructure monitoring we already run?
Traditional monitoring tells you a system is up. It can't tell you an agent retrieved stale context, reasoned its way to a plausible but wrong conclusion, and acted on it — because nothing errored. Agent trust monitors correctness and behavior, not just availability.
Is this AI security?
No, Monte Carlo provides agent trust from the perspective of performance, quality, reliability, and accuracy. Security-side "agent trust" is about identity and authorization (is this agent who it claims to be?).
Our agents run across several frameworks and clouds. Does that matter?
No. Instrumentation for agents is OpenTelemetry-based and platform-agnostic, with 50+ native integrations across the modern data stack.
Where does our telemetry live?
In your own cloud account — either your warehouse or lakehouse, or a self-hosted trace store you deploy. Sensitive trace data stays inside your perimeter for security, compliance, and auditability.
What does this take from my teams to stand up?
For agents on Snowflake Cortex or Databricks, there is no additional instrumentation required. Monte Carlo reads trace data through your existing warehouse connection. For agents you've built yourself, your team deploys the trace store into your own cloud with one Terraform module and instruments with our SDK, which the Agent Toolkit handles from your editor. Either way, the work is front-loaded: new agents appear automatically as they start emitting traces, and Monte Carlo's internal Operations Agent recommends coverage to expedite onboarding.
How can Monte Carlo help me justify further AI investment?
Monte Carlo tracks key performance and cost-related metrics for your agents, including token usage, latency, error and retry rates, and reliability trends over time. These are reported per agent, in aggregate, and can be used, in conjunction with other data, to correlate how agentic failures correlate to poor productivity, efficiency, or customer outcomes. While Monte Carlo doesn't calculate your business case, it gives you useful operational insights with real production numbers instead of pilot estimates.
How long does onboarding actually take?
Setup and coverage on your first domain runs 30 days end to end, with monitors live and detecting by week 3. A single well-structured domain can go from plan to production in a day. What sets the pace is your side of the work: naming the launch team, shortlisting priority assets, and granting integration access.
What is a monitoring plan?
It's the agent's proposal for what to monitor in a domain. Rather than configuring monitors agent by agent or table by table, you point it at a domain. It ranks assets by criticality, deep-dives the highest-priority ones, and proposes a set of monitors, each with a plain-language reason. Nothing deploys until a human approves it.
Do agents deploy monitors without asking?
No. Recommendations are never deployed automatically. You review the plan and enable all of it, or a subset by database or by monitor.
How long does the agent take to generate a plan?
Generation runs unattended and needs nothing from you while it works. Expect a few hours for most domains. The agent spends up to one to two minutes per qualifying table, so a large domain can run considerably longer.
What makes a good plan?
Domain hygiene is the biggest lever. Give domains meaningful boundaries — medallion layers, product lines, or data-mesh ownership. Assign every related table, dashboard, and asset to the domain, since coverage is only as complete as what the agent can see. Enable data sampling if you want field-level validation monitors rather than table-level ones only. And describe the use case in your own words when you create the plan: business purpose, critical tables, known failure modes. Context measurably improves accuracy.
How do agent-deployed monitors interact with the ones we already have?
They coexist. Monitors created from a plan are attributed to the Agentic Platform Agent user, so you can tell them apart from ones your team authored by hand. You can also export a plan as YAML and manage the monitors in Monitors as Code alongside the rest of your version-controlled configuration.
Can we control cost?
Yes. The plan shows an estimated daily credit cost for the whole plan and for each individual monitor before you enable anything, so you're choosing coverage against a number rather than finding out later.
What can agents see?
A plan runs on the permissions of the user who creates it, so it can only see and plan against assets that user can access. Full detail on security, data handling, and privacy is in the AI features documentation.
Does this work for AI agents in production, not just data?
Yes. An agent-first rollout is a common shape: onboard your first two or three production agents in week 2, with output evals, behavior tracing, and performance and cost monitoring, then work upstream to the data those agents depend on in week 3.
What happens after 30 days?
The 30-day readout closes month one. From month two, ongoing work runs through a quarterly cadence with a dedicated field engineer: monitor strategy and optimization, coverage expansion into new domains, and agent readiness reviews.