Built for AI engineers scaling agents past pilot
You shipped the agent. Now it has to hold up in production.
Catch the failures your evals can’t see
Agents don't crash, but they will degrade. Bad context, hallucinated outputs, and silent behavioral drift all return a clean 200.
Find the root cause in minutes
Go from a bad output to the exact span that produced it — and the source data behind it.
Scale agents while keeping MTTR low
See token spend, latency, and error patterns in aggregate and with automated tooling, so adding agents doesn't mean more engineering load.
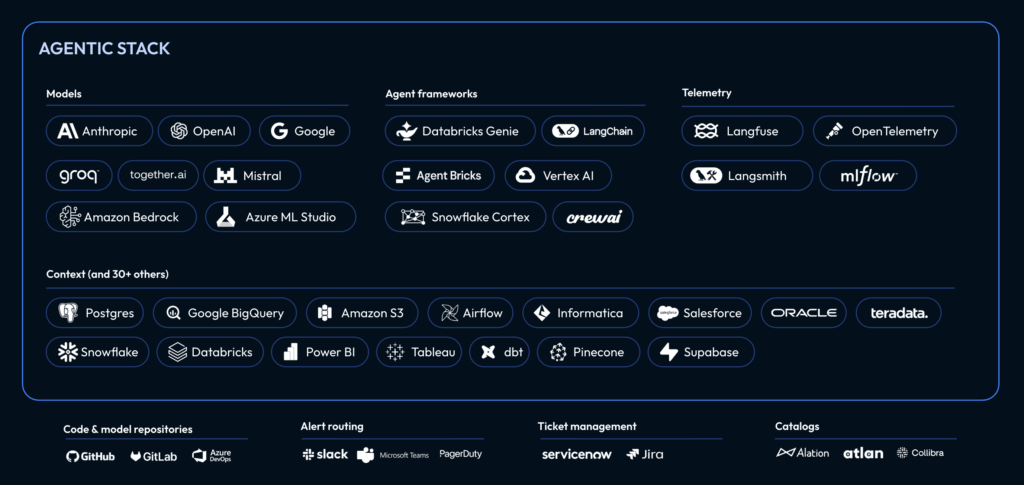
Works with your entire agent stack
Your agents don't live in one place, and neither does the risk. Monte Carlo plugs into every layer your agents depend on — the models they call, the frameworks they run on, the telemetry they emit, and the data and context they pull from — with native integrations rather than glue code you have to maintain.
That coverage is what makes the rest possible: you get lineage from raw data in the warehouse all the way to the action an agent takes, so when something breaks you can trace it back to the exact pipeline failure, model change, or context drift that caused it.
Everything you need to trust the agents you put in front of people
Evals get you to launch. Monte Carlo gets you to scale.
Know when your agents are wrong, not just when they're down
An agent can return a fast, error-free, completely incorrect answer. Monte Carlo watches the four things that actually determine whether you can trust it:
- is it pulling the right information?
- is it running efficiently?
- is it behaving the way you intended?
- and is the final answer good enough to act on?
Most tools only check the last gate.
Find the root cause in minutes, not days
When something goes wrong, you get the answer instead of a search. Monte Carlo shows you exactly where the agent went off course and traces it back to the source — so you know whether to change the prompt, switch the model, or fix a broken pipeline upstream, without a week of guesswork or a war room.
Keep AI spend predictable as you scale
Quality checks that cost as much as the agent itself aren't a strategy. Monte Carlo gives you a reliable read on how your agents are performing without evaluating every single call, and shows you where the money and the latency are actually going. Add agents without watching the bill.

Enterprise-grade from the first agent
Agent observability means handling prompts, retrieved context, and outputs — some of your most sensitive data. Telemetry stays in your own environment, with granular access controls and audit logging. Get the visibility without the security review becoming a six-month detour.
How Axios ships reliable AI agents in production
Axios's AI team set out to remove friction from the newsroom's most tedious work, freeing journalists to focus on reporting. As they scaled past a dozen LLM-powered agents, they wanted the same confidence in their agents that they already had in their data.
Agent Observability, instrumented in just a few lines of code via Monte Carlo's OpenTelemetry SDK. Axios now sees prompt and response traces, token usage, latency, and evaluation scores over time — right alongside the data and ML monitoring they already rely on, in one familiar interface.
Axios
“We were able to get started with two lines of code.”
 SS
Shreye Saxena
Senior Data Scientist, Axios
Ship agents. Not fire drills.
Connect in minutes, start monitoring out of the box, and scale coverage as your agent fleet grows.
Trusted by 400+ enterprises