
Scale your agents, not your risk
Monte Carlo is the agent trust platform that helps you realize the true value of your AI programs by monitoring, troubleshooting, and improving your agents and their underlying data.
Production visibility into data and agents
See every agent you have operating in production, including the data they access, with the ability to trace and audit all runs.
Cost insights beyond inference
Prove the value of your AI program and eliminate token waste with clear visibility into the cost, latency, and reliability of every agent workflow.
One observability standard, every deployment
One platform across every team, framework, model, and cloud — instead of a different monitoring story for every agent your org ships.
Close the trust gap keeping your agents stuck in pilot
The gap between agents stuck in pilot and successful AI in production is trust, and that requires real evidence: knowing when an agent is failing, why it's failing, what data it has access to, and whether it's getting better or worse with every run.
That trust gap has a cost you can already see on your P&L: some agents never leave pilot because no one will sign off on them.
Monte Carlo closes the trust gap across your entire agentic stack, giving you visibility into the data feeding your agents and the agents themselves.
Four dimensions — context, performance, behavior, output — are monitored continuously in production.
Control your AI spend with visibility beyond the inference bill
Agent costs don't scale linearly with value, and model invoices don't shed light on cost multipliers driven by agent behaviors. Monte Carlo does.
Understand AI cost at the token level as it’s generate
Monte Carlo measures token usage at the grain where it's created — the individual span. Every LLM span carries its own token count, and you can raise the grain to the whole trace or the whole conversation, segment by various fields, and filter down to a single workflow, task, or span.
- Set a metric monitor to keep track of it: mean, max, sum, or percentile aggregations to catch the expensive tail. One runaway run doesn’t move an average.
- See when token metrics are anomalous with either a manual threshold or an ML-generated one that learns the agent’s normal consumption range.
- Catch runaway sequences with trajectory monitors that flag when a tool is called more often than it should be, in an order it shouldn’t be, or with a step missing.
Unified visibility across your data and agents
When an agent produces a wrong output, the instinct is to look exclusively at the agent layer. Many failures, however, originate in the data layer: a schema change breaks a pipeline feeding the knowledge base, or a volume anomaly degrades retrieval quality over time.
LLM-native monitoring tools stop at the model layer and never see these issues.
Monte Carlo pioneered data observability in 2019 and extended it to encompass the entire agentic stack. The same graph that traces your agents monitors the tables, pipelines, and models they depend on — so when an answer is wrong, you can follow it to its true origin point.
How it works
Monte Carlo instruments your agents with OpenTelemetry, stores the trace data in your own cloud account, and queries it through a serverless workload running in your environment. The trace store of record stays inside your perimeter and Monte Carlo keeps no persistent copy — so you get one operating picture of your agents and the data feeding them without handing your prompts and outputs to a vendor's retention policy.
-
Instrument
Your agents emit OpenTelemetry traces through the Monte Carlo SDK. Our skill in the public MC Agent Toolkit does the work from your AI code editor for you, installing the SDK, placing the decorators, and verifying traces are flowing. Agents built on Snowflake Cortex or Databricks connect seamlessly.
-
Deploy
One Terraform module stands up the trace platform in your account: an OpenTelemetry Collector to receive spans and a ClickHouse cluster to store them. Runs on EKS, AKS, or GKE. Evaluations run against your own cloud’s LLM service. The model scoring your agents is yours to select, operating under your account’s own security and retention controls.
-
Connect
Monte Carlo queries the trace store through the Monte Carlo Agent, a serverless workload in your account with private network access to the cluster. It only reads telemetry and appends to the evaluation job queue — it cannot write telemetry, run DDL, or manage access. Instrumented agents appear on the Agents page on their own as soon as their traces land in ClickHouse.
-
Monitor
Every run arrives as a trace: a tree of spans containing prompts, context, completions, token usage, latency, model metadata, tool calls, and errors. Monitor it via evaluations for output quality and correctness, metric monitors for performance, trajectory monitors for tool-call sequences, and validation monitors for per-trace and per-span constraints. Do this manually or via Monte Carlo’s Agentic Operations.
Works across your diverse data and AI stack
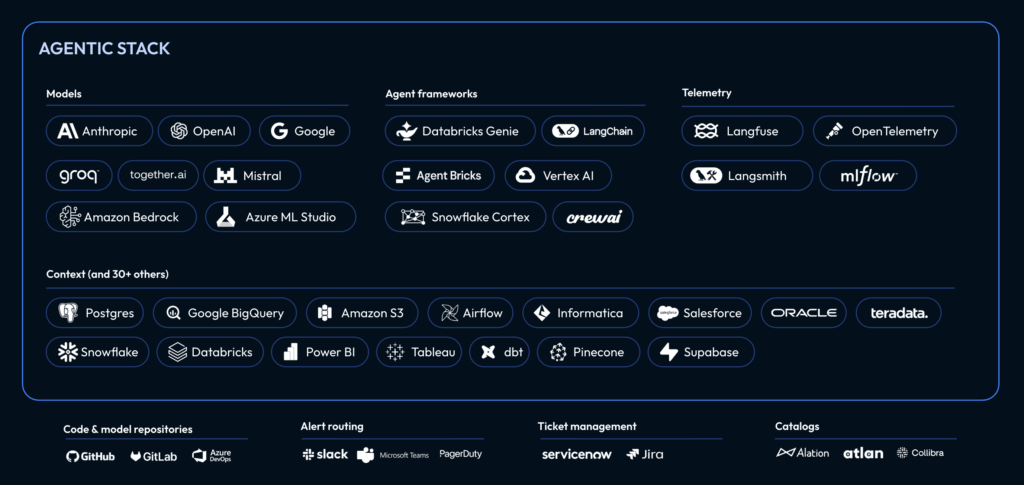
Monte Carlo supports the heterogeneous data and agent ecosystems that enterprises rely on, so you can take advantage of Agentic Onboarding without having to change anything about your existing stack.
Trusted by 400+ enterprises deploying AI at scale
Reliability isn't theoretical for these teams. It's operational.




Axios
“We were using Monte Carlo to observe our data ecosystem and our ML model predictions, so being able to incorporate agent observability workflows in just a few clicks with the same familiarity for how we set up our monitors, and alerts, and get observability across our whole platform was attractive.”
 SS
Shreye Saxena
Senior Data Scientist at Axios
Nasdaq
6,000
reports a day
35
services
2,200
users
Reliability at that scale isn’t a tooling choice, it’s an architectural one.
JetBlue
+16 pts
internal “data NPS,” year over year
Improved by operationalizing observability and measuring the outcome.
Questions CIOs and CTOs ask us
How is this different from the APM and infrastructure monitoring we already run?
Traditional monitoring tells you a system is up. It can’t tell you an agent retrieved stale context, reasoned its way to a plausible but wrong conclusion, and acted on it — because nothing errored. Agent trust monitors correctness and behavior, not just availability.
Is this AI security?
No, Monte Carlo provides agent trust from the perspective of performance, quality, reliability, and accuracy. Security-side “agent trust” is about identity and authorization (is this agent who it claims to be?)
Our agents run across several frameworks and clouds. Does that matter?
No. Instrumentation for agents is OpenTelemetry-based and platform-agnostic, with 50+ native integrations across the modern data stack.
Where does our telemetry live?
In your own cloud account — either your warehouse or lakehouse, or a self-hosted trace store you deploy. Sensitive trace data stays inside your perimeter for security, compliance, and auditability.
What does this take from my teams to stand up?
For agents on Snowflake Cortex or Databricks, there is no additional instrumentation required. Monte Carlo reads trace data through your existing warehouse connection. For agents you’ve built yourself, your team deploys the trace store into your own cloud with one Terraform module and instruments with our SDK, which the Agent Toolkit handles from your editor. Either way, the work is front-loaded: new agents appear automatically as they start emitting traces, and Monte Carlo’s internal Operations Agent recommends coverage to expedite onboarding.
How can Monte Carlo help me justify further AI investment?
Monte Carlo tracks key performance and cost-related metrics for your agents, including token usage, latency, error and retry rates, and reliability trends over time. These are reported per agent, in aggregate, and can be used, in conjunction with other data, to correlate how agentic failures correlate to poor productivity, efficiency, or customer outcomes. While Monte Carlo doesn’t calculate your business case, it gives you useful operational insights with real production numbers instead of pilot estimates.
See how enterprises put agent trust into production
Connect in minutes, start monitoring out of the box, and scale coverage as your agent fleet grows.